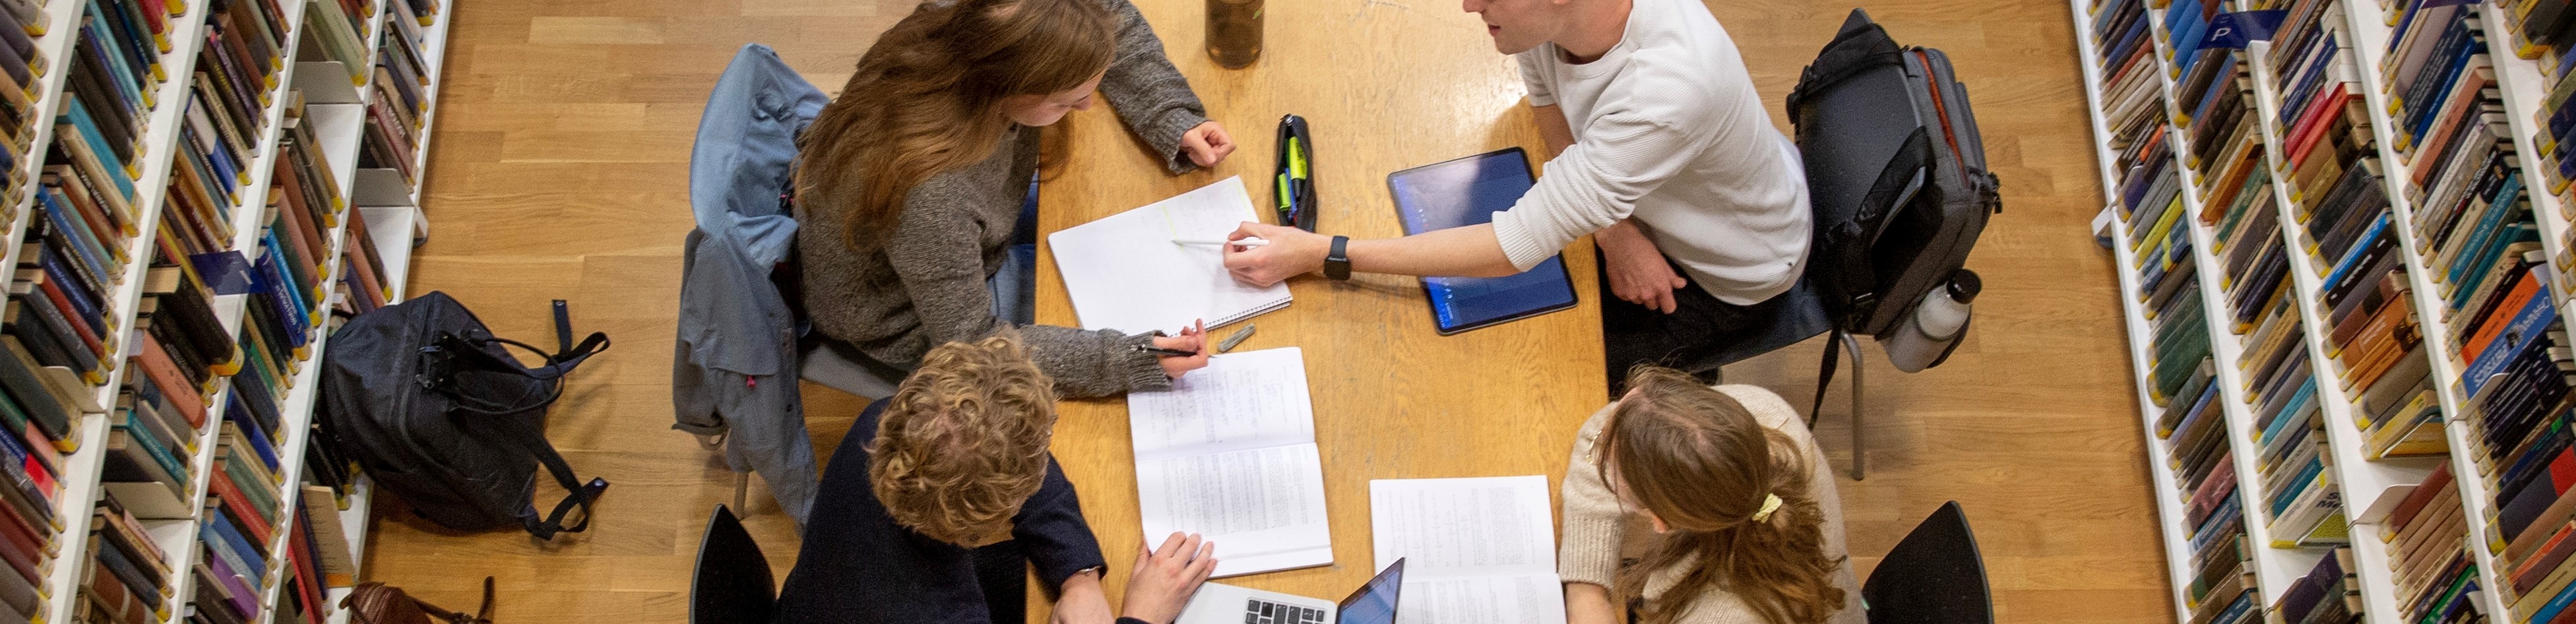
The students develop solutions to predict the categorisation of two large data sets using machine learning. The solutions are part of a class competition to find out who can come up with the most precise solution. This mimics real research strategies in machine learning with data analysis.
We wanted to make our assignment resemble a real machine learning competition. The advantage is that it encourages the students to think about how to assess performance in an impartial manner and they test real research strategies in the field.
After the course, the students will have the necessary theoretical and practical background to work with modelling and understanding different types of genomic data sets, with focus on predictability and classification. The students will develop detailed knowledge about current statistical learning methods, which are specially adapted to (large) genomic data sets.
THE PROCESS | |||
Group work |
| ||
Partial submission with feedback from the teache |
| ||
Adapting their model |
| ||
Competition decision |
| ||
Our experience is that the opportunity to work in groups while having an element of competition in the exercises is highly motivating for many.
At the same time, the design forces students to use key elements from machine learning. Students get unbiased estimates of test error using e.g. cross validation and learn how to compare models - both theoretically and practically.
At the end of the course, the students also learn how to combine models – and the final assignments are very often combinations of models with different biases and variances.
"Gamification" has a strong motivating effect on many people. Furthermore, students on a machine learning course are highly motivated if they have tried something identical to a real ML competition (kaggle.com).
The advantage is also that we do assignments that we, as teaching staff, find fun/motivating.
Not everyone thinks competition is fun. Some students do quite poorly in the competition and never really get fully involved.
Finding data that is close to the research and also good/easy enough to use for teaching is often challenging. There are often challenges with 'real' data, making it frustrating for students to work with it.
| Educator | Palle Villesen, Thomas Bataillon, Asger Hobolth |
| Faculty and department | NAT, Bioinformatics Research Centre (BiRC) |
| Degree programme | Bioinformatics |
| Course/subject | Statistical and Machine Learning in Bioinformatics |
| Level of study | Master’s |
| Teaching format | Lecture, Classroom instruction |
| Extent | Course |
| How was the case conducted? | Onsite in-person teaching (including the use of Brightspace) |